


The single-model video production market is exceptionally crowded. Performance marketers, indie creators, and social media managers are locked in a continuous loop of asset generation.
They need dozens of fifteen-second visual hooks before lunch. However, traditional post-production pipelines are painfully slow.
In order to fix this bottleneck, ShenShu Technology, in collaboration with Tsinghua University, launched Vidu AI.
Vidu AI is a dedicated video-first motion synthesis network. Unlike generic and all-in-one AI suites that try to handle image editing, copywriting, and vector tracking simultaneously, this platform prioritizes cinematic and motion-first clip generation.
The technical architecture is built directly on a novel Universal Vision Transformer (U-ViT) model framework.
By natively combining diffusion processing with transformer scalability, it bypasses traditional frame-to-frame rendering glitches.
For multimedia teams evaluating production infrastructure, understanding this transformer network, its specialized character mapping, and its 2026 feature updates is critical for scaling studio workflows.
Technical Architecture: Understanding The U-ViT Core
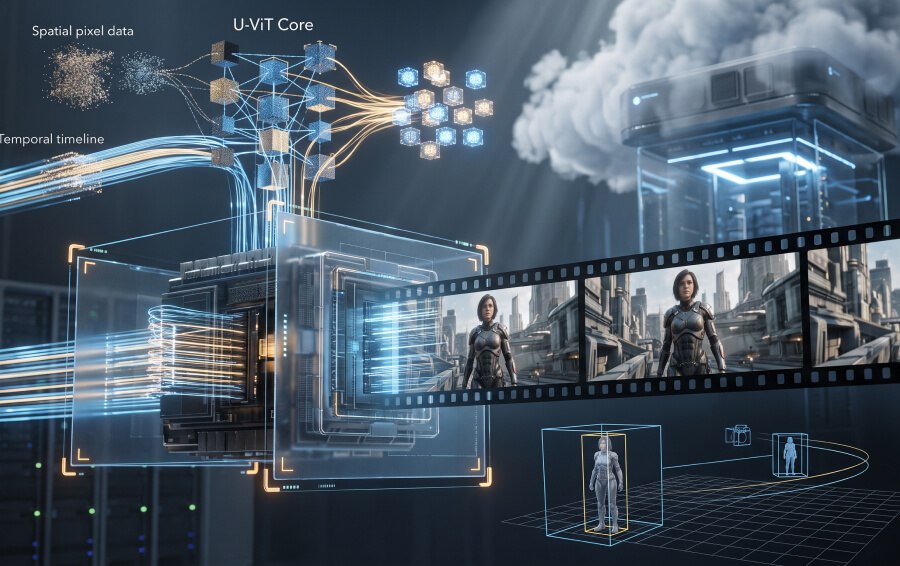
Most legacy AI animation tools rely on basic diffusion networks to guess what the next frame should look like.
This method frequently leads to visual tearing, warping, or background melting during rapid camera pans.
The Scalability Model
The platform addresses these issues through its open-source U-ViT architecture. This design treats spatial pixels and temporal timelines as unified data tokens.
Instead of stitching individual frames together, the platform processes the entire sequence in a single cloud computation window. As a result, the model generates cohesive and high-definition sequences up to 16 seconds long.
Semantic Image Tracking
The transformer architecture excels at keeping character geometry stable over time. When you prompt a camera to spin around an object, the model maps out the three-dimensional boundaries of the subject beforehand.
This strict spatial tracking means your characters, vehicles, and background settings retain their exact physical forms. That is, even during aggressive and high-speed camera movements.
Core Generation Engines And Asset Customization
The workspace focuses entirely on streamlining the path from a raw visual brief to an acceptable MP4 download.
The production environment divides its rendering pipelines into three main workflows.
Core Generation Engines At A Glance
| Creation Mode | What You Provide | Engine & Core Mechanism | Best Used For |
|---|---|---|---|
| Text-to-Video | Written description, ratio, and scene duration. | Standard diffusion rendering. | Abstract background B-roll and fast conceptual scene mapping. |
| Image-to-Video | A distinct starting photo and a separate end frame. | viduq3-turbo trajectory calculator. | Seamless product transitions and animating static ad layers. |
| Reference-to-Video | Up to 7 reference photos of a single subject from varied angles. | viduq3-mix feature consistency indexing. | Multi-shot character continuity and narrative storytelling. |
Text-To-Video Mode
Users input a direct descriptive prompt, select an aspect ratio, and choose their target duration.
The engine translates the prompt variables into short and highly stylized clips, which makes it a robust choice for abstract background B-roll or rapid fantasy concept mapping.
Image-To-Video Mode
This pipeline is engineered for performance marketers who want to breathe motion into static advertising assets.
Designers can upload a distinct first frame and a completely separate end frame.
The platform's viduq3-turbo rendering engine calculates the optimal physical trajectory between the two images. As a result, it creates smooth, personalized product transitions that protect brand assets.
Reference-To-Video Mode
The standout feature for narrative creators is the multi-reference consistency engine.
Users can upload up to seven distinct reference photos detailing a specific character, clothing set, or object from unrecorded angles.
The viduq3-mix engine indexes these traits. This allows you to place that exact character into completely new environments while preserving their facial features across multiple sequential shots.
Token Allocation And Plan Tiers
The system uses a straightforward and credit-based billing system.
While the baseline entry points are highly competitive, production managers must note that premium high-speed models consume your monthly credit wallet significantly faster.
Budget Structures And Operational Capabilities
| Pricing Tier | Entry Cost (Billed Annually) | Monthly Credit Balance | Included Rendering Capabilities |
|---|---|---|---|
| Free Tier | $0 | 80 Credits | Caps outputs at 720p resolution; includes a visible brand watermark in the corner. |
| Standard Plan | $8 / Month | 800 Credits | Unlocks full 1080p HD, removes watermarks, enables 8-second clips, and permits commercial usage rights. |
| Premium Plan | $28 / Month | 4,000 Credits | Enables fast-pass priority cloud queues and early access to beta generation models. |
| Ultimate Plan | $79 / Month | 8,000 Credits | Features ultra-fast processing speeds plus unlimited video generation during non-peak hours. |
Production Strengths And Structural Bottlenecks
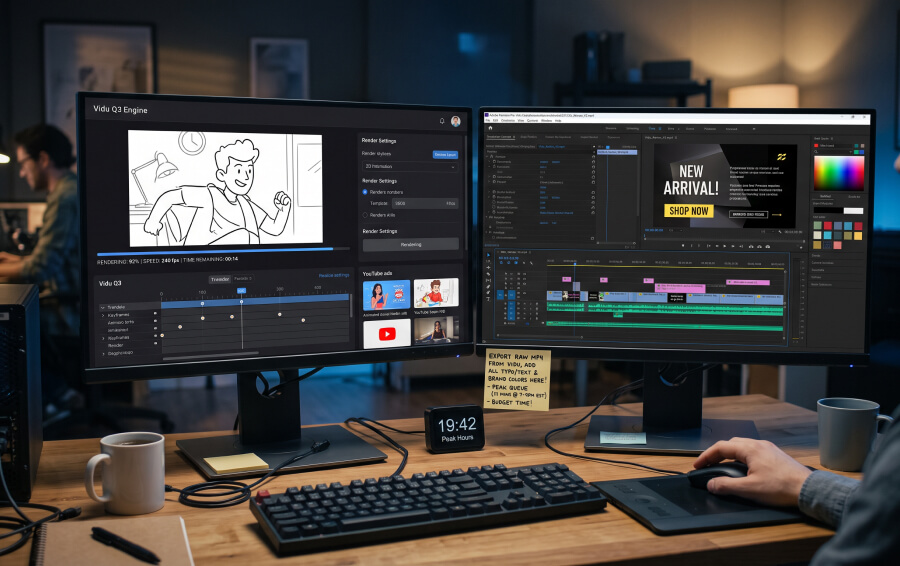
The deployment of a single-model motion renderer requires balancing immense rendering speed against the realities of modern post-production requirements.
The Competitive Edge
The clearest advantage of the platform is its sheer speed as well as its focused dashboard.
Junior content operators can scale up social media video ads or faceless YouTube clips within minutes without fighting a confusing wall of unrelated editing tools.
Furthermore, current testing on the native Vidu Q3 engine showcases excellent processing for 2D line art and animation styles. As a result, this makes it a unique asset for indie animation studios.
The Operational Limits
However, creators must realize that the platform is a specialized motion renderer, not a complete post-production pipeline.
It does not handle typography overlays, interactive captions, end cards, or precise brand-kit color matching.
If your brief includes heavy textual elements, you must export the raw MP4 file. Followed by this, pull it into external editors like Premiere Pro or specialized multi-asset design layers to add your copy.
Additionally, during peak US evening hours, standard public queue times can stretch up to eleven minutes, which is an operational time cost teams must actively budget.
Strategic Market Placement
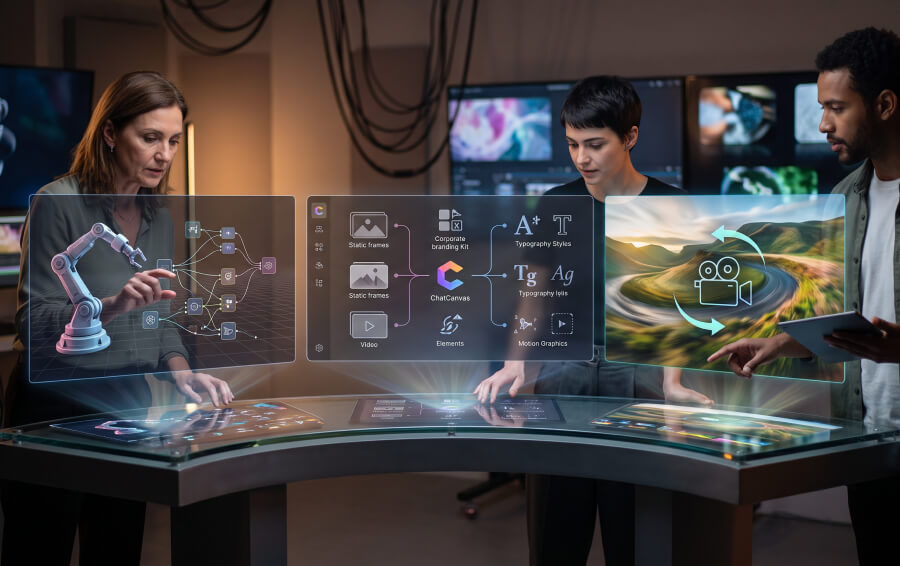
Your studio's distribution strategy may require a completely unified design ecosystem rather than a dedicated video renderer.
Consequently, tracking alternative workflows is essential for maintaining agility.
Runway Gen-3 Alpha
The current industry standard for professional film studios requiring deep keyframe customization and complex camera adjustments.
It provides advanced control nodes, though it carries a significantly steeper learning curve for junior editors.
Luma Dream Machine
A highly competitive alternative that specializes in rapid camera sweeps, sweeping landscape renders, and prompt adherence.
It is frequently deployed by creative teams looking for quick, high-fidelity environmental backgrounds.
Lovart Design Agent
Unlike specialized motion engines, this alternative focuses on multi-asset campaign management.
Utilizing its specialized ChatCanvas interface, it handles static frames, corporate branding kits, and on-screen typography alongside movement.
Therefore, it serves as a broader production workspace.
Navigating Your Production Workflow
In conclusion, Ultimately, Vidu AI functions as a highly efficient, speed-first asset accelerator for the modern media economy.
Furthermore, it cuts out the friction of traditional video production by trading complex timeline menus for a clean, credit-driven rendering engine.
The platform leans heavily into character consistency through multi-reference image mapping. Thus, it effectively solves the core instability issues that historically made AI video unusable for serious storytelling.
Your production manager must plan around peak-hour queue delays and maintain a separate software workflow for typography editing.
Provided these conditions are met, this transformer-driven suite stands as a powerful tool for scaling high-volume digital video channels.